Cortega AI Governance Platform — Model Recommendations, Benchmarks & Model Upgrades
CCortega AI Governance Platform

Pick your next model with Cortega Model Intelligence.

Cortega measures every model against your own traffic, ranks upgrade candidates, conducts multiple studies, and performs safe upgrades. Self-managed, on infrastructure you control.

YOUR TRAFFIC Requests, tokens, spend, and workload — per model, last 30 days RECOMMENDATIONS Ranked candidates top pick + alternates score, cost, why / why-not recomputed every 30 days STUDY IT Full AI Bench run, guardrails on, on the exact candidate model AUTHORIZE Wins. Route it, per team. EVERY STUDY IS A PERMANENT ROW Nothing merges or recomputes past results. Re-study creates a new row with today's numbers; the old row stays exactly as it was. Comparing "did this model get better" is reading two rows. Nothing in production changes until you decide to authorize it.
How it works

Four steps

01

Cortega matches your AI usage against Model Intelligence

Cortega tracks model performance, volume, token counts, spend, and latency. Model Intelligence service collects performance benchmarks from multiple sources.

02

Cortega ranks model candidates

Cortega Model Recommendations builds a ranked list using your workload information.

03

Cortega runs a Model Study on model candidates

“Study this model” schedules a full AI RedTeam and Bench analysis against. the candidates

04

You Authorize the switch and Cortega executes it safely

Cortega uses its advanced routing to safely inject the new model into production.

What gets measured

No more guesswork

Model Performancemeasured per run usings industry standard benchmarks, run on your configuration
Latencyaverage and per-run, on the gateway you already operate
Errorstracked per study run, rolled up alongside pass rate
Costcost estimate and comparison against the model it would replace
Cortega LLM and MCP Benchmarks

Industry and agentic security suites

01

Industry suites

General safety, healthcare, finance, legal, and privacy / PII — scored on your configuration.

02

Agentic security

Jailbreak and prompt-injection techniques, multi-turn escalation, many-shot jailbreaking, and MCP tool-call poisoning — the same red-team suites AI Bench runs against your live guardrails.

03

Both LLM and MCP

A study spans LLM Benchmark and MCP Benchmark together — a candidate is judged on chat behavior and on how it handles a poisoned tool result.

See AI Bench →
In the console

Recommendations & workload
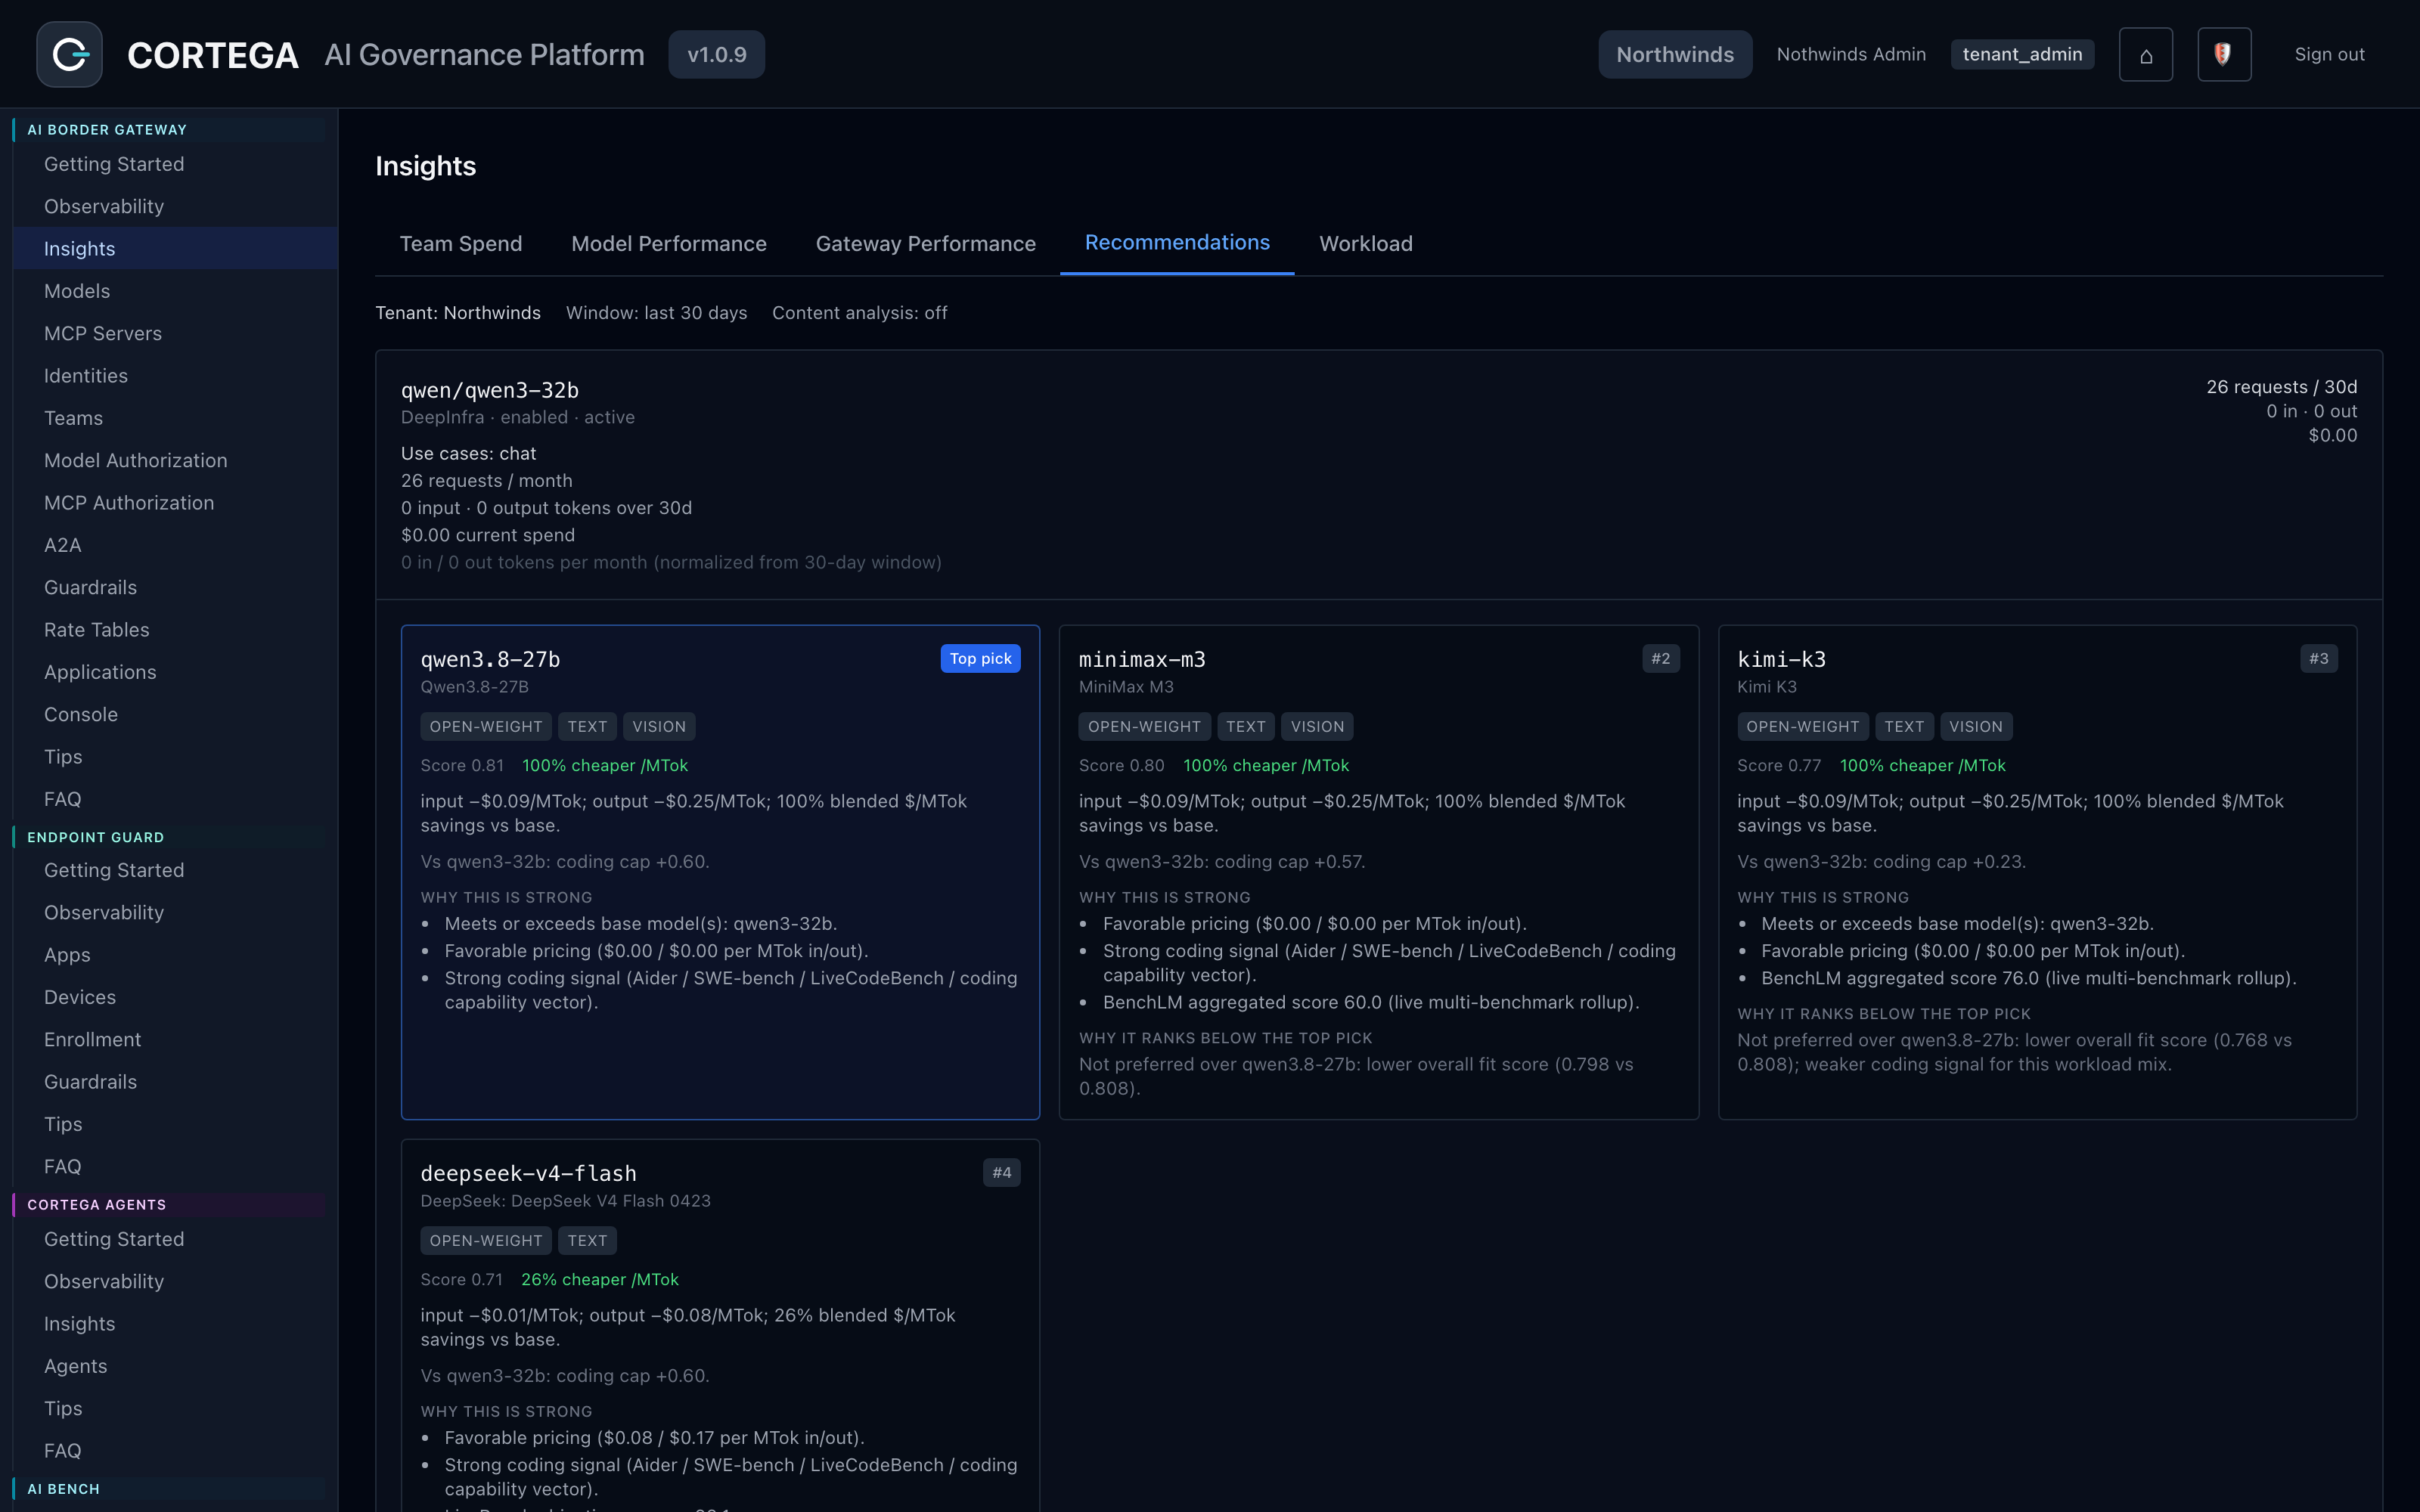
Recommendations · ranked upgrade candidates
Cortega Recommendations: measured 30-day workload per model, with ranked upgrade candidates, score, and cost comparison
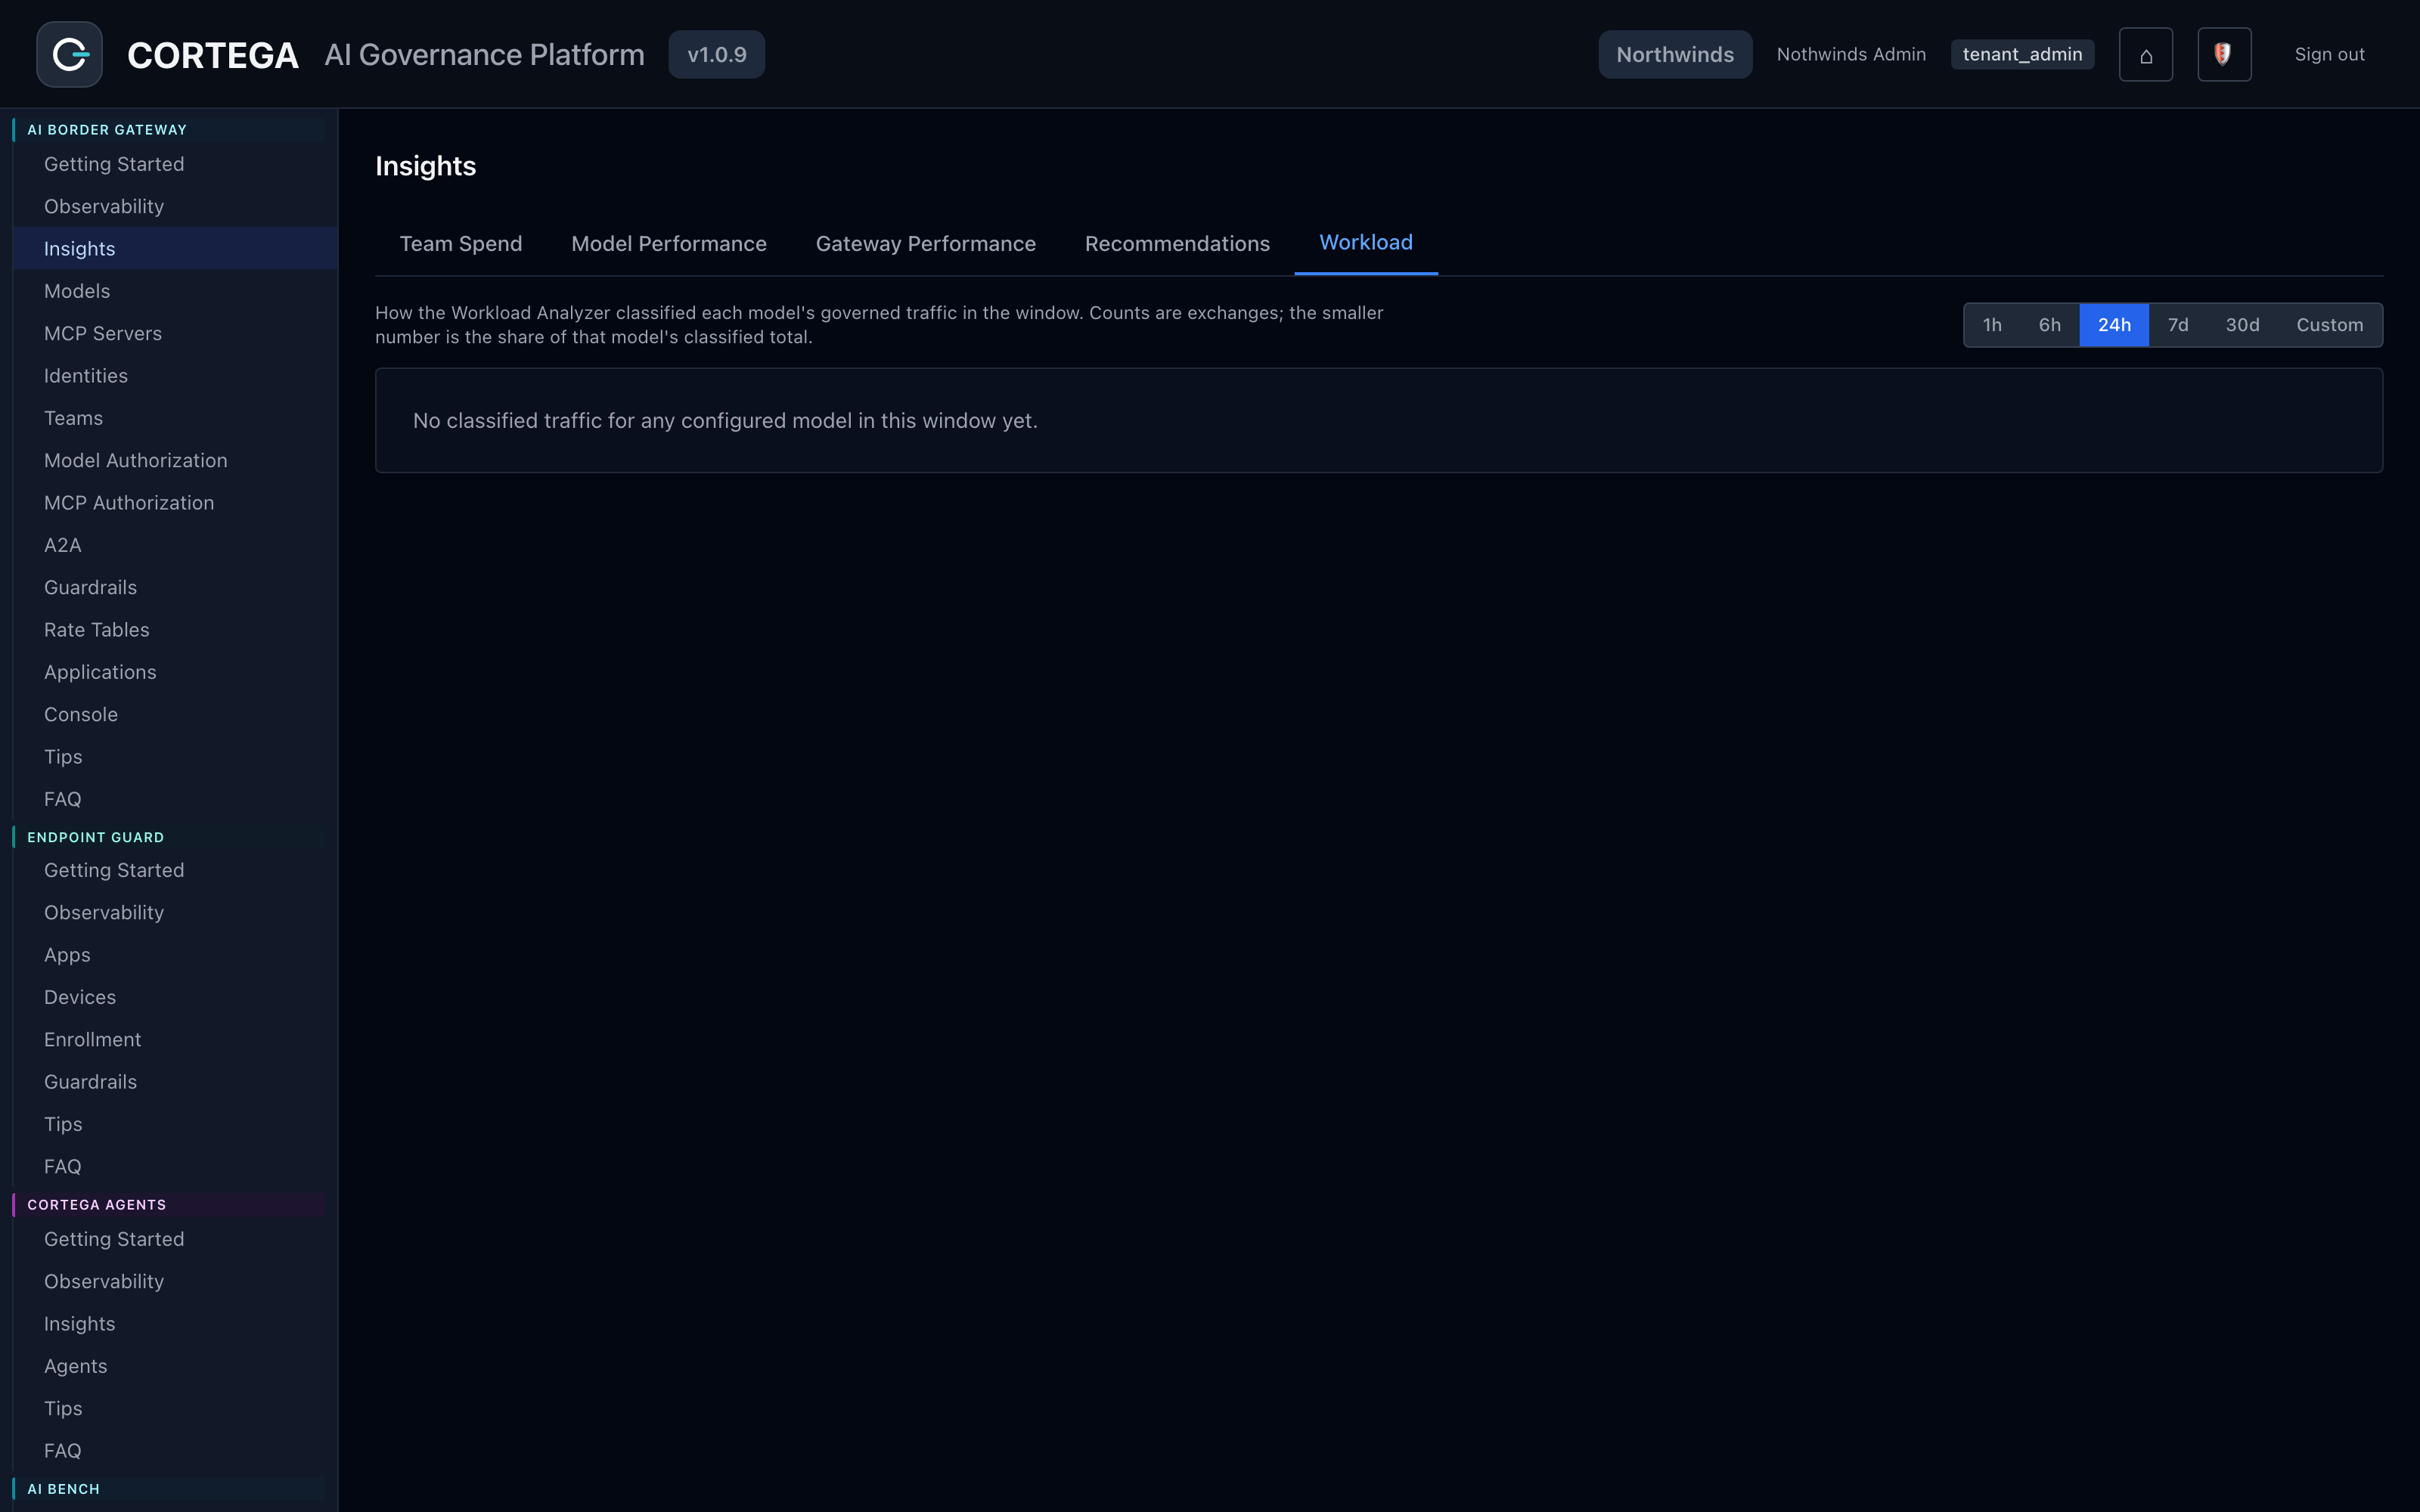
Cortega Workload report: traffic classified into productized workload categories
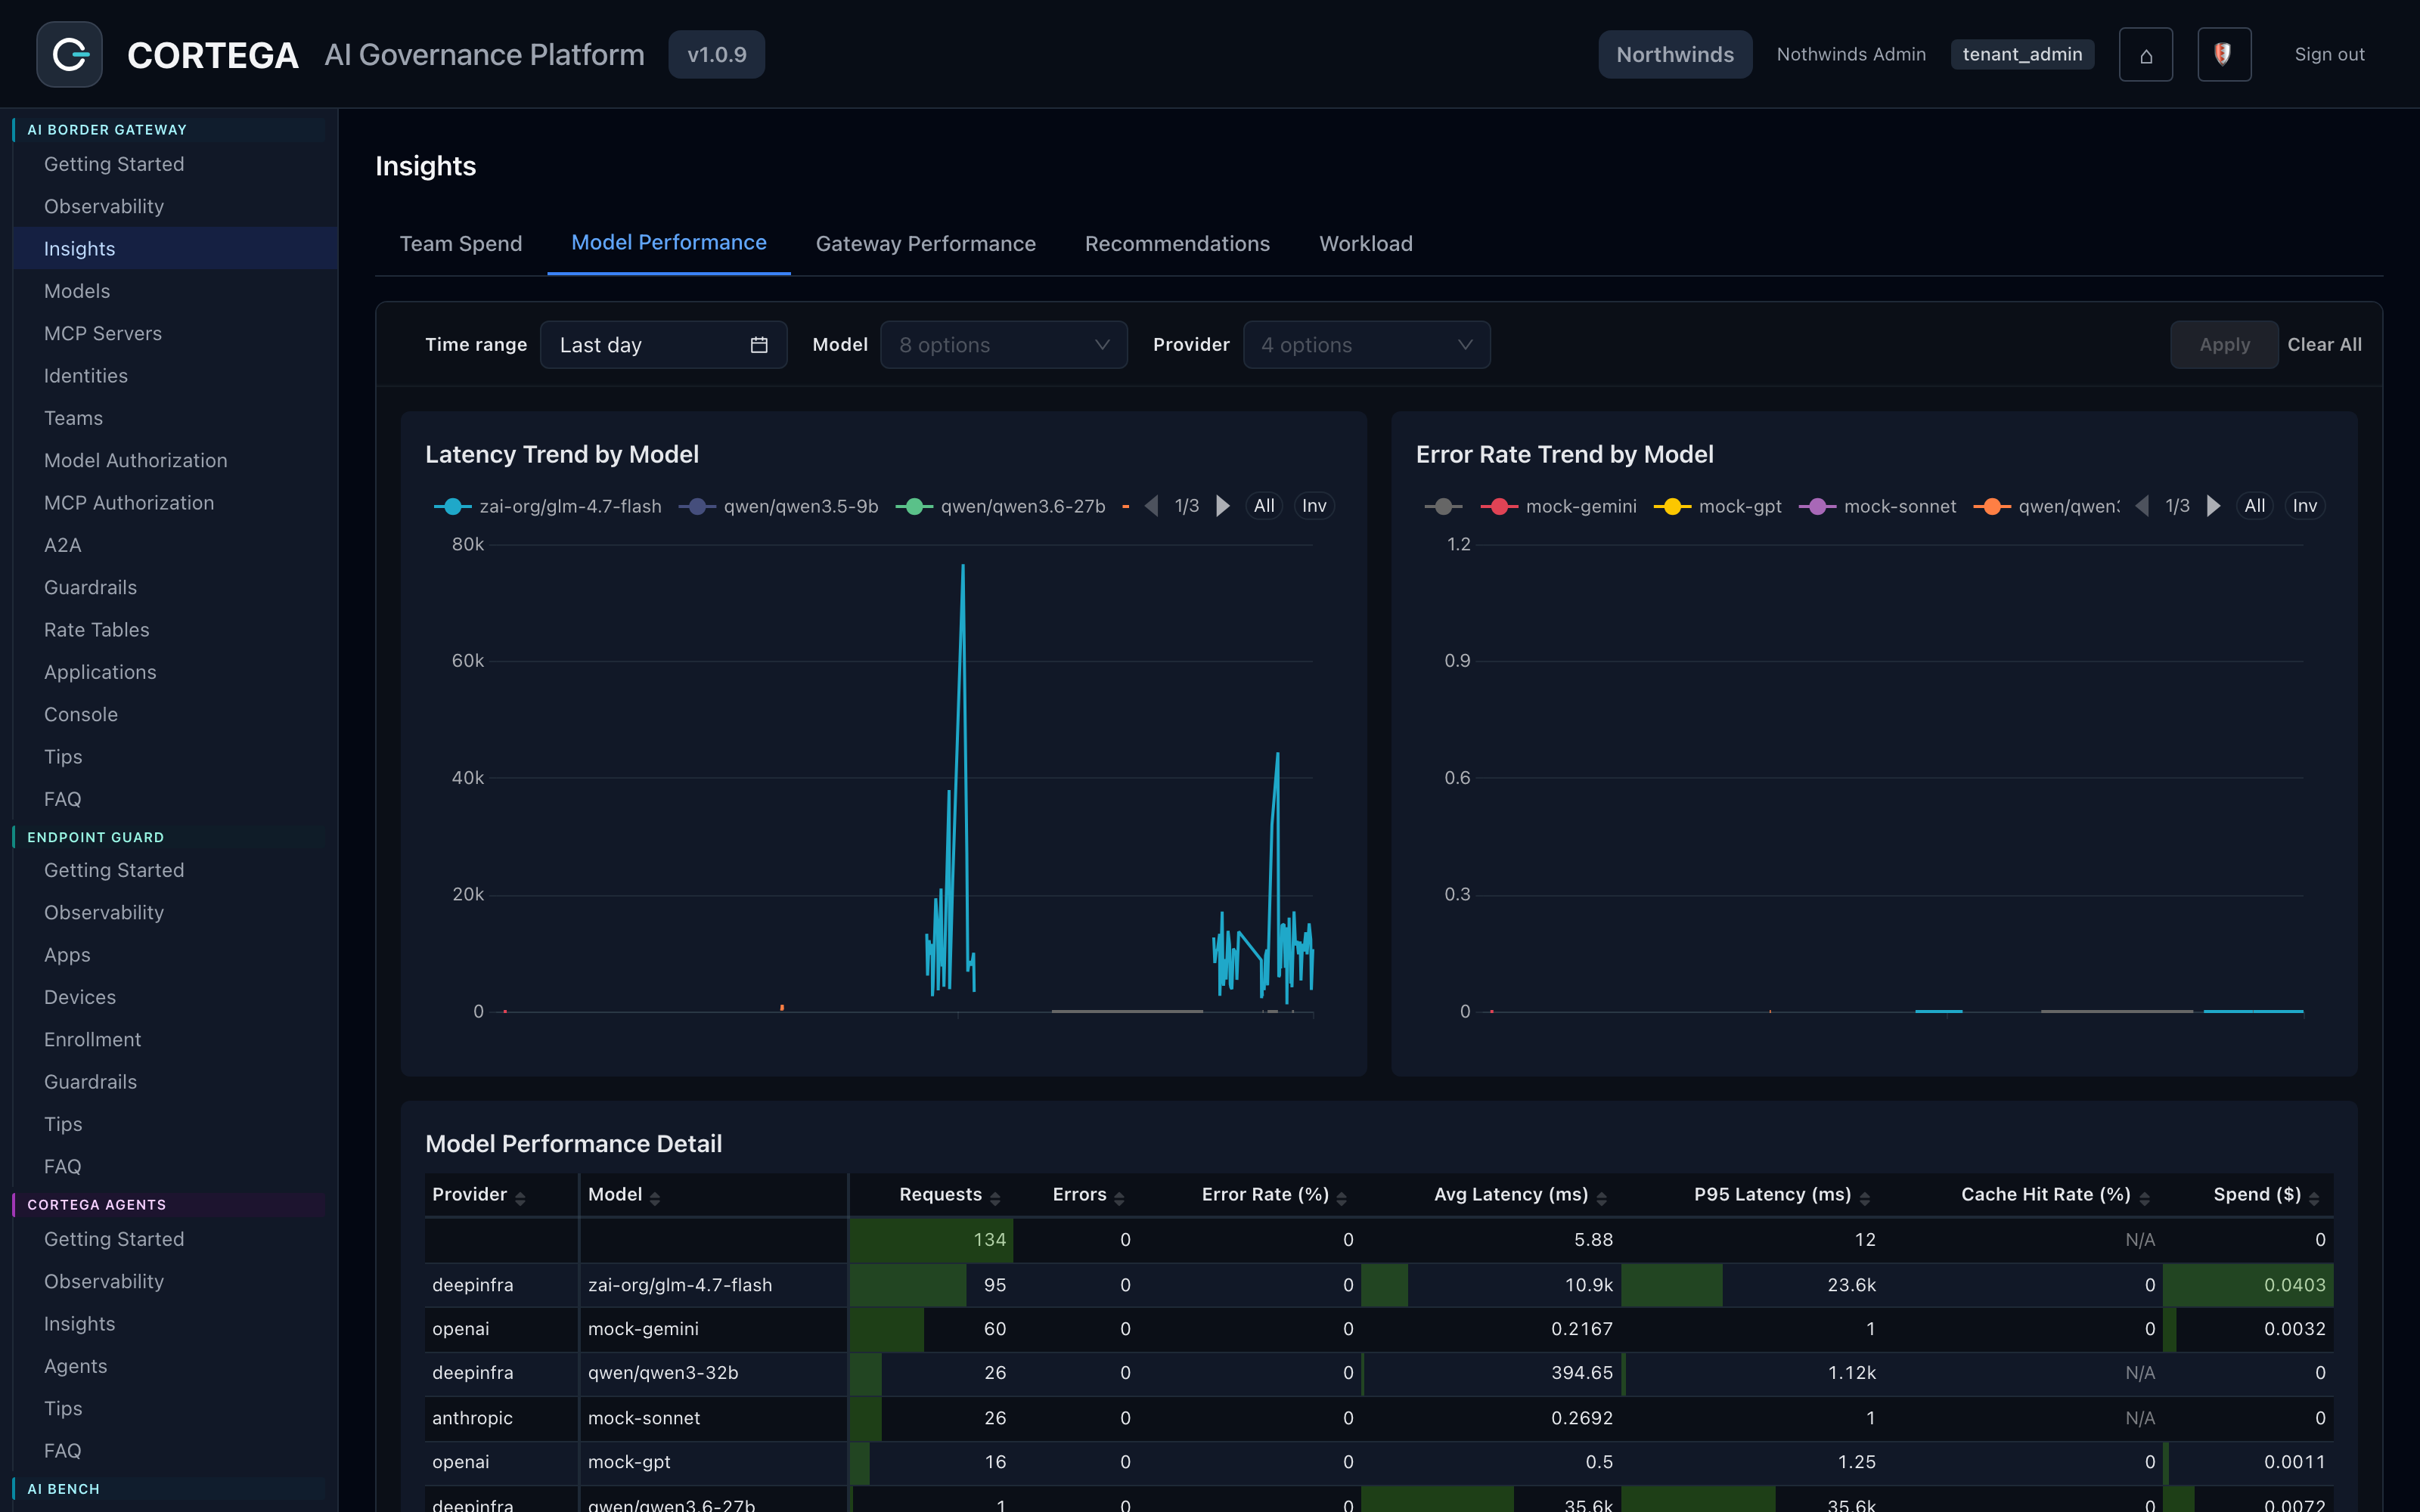
Cortega Model Performance: latency, error rate, and cost per model

From the Cortega console · Insights.

Get started

Switch models on your own evidence

Try it yourself

Foundation is free — one gateway, standard guardrails, no time limit.

Talk to us

See it ranked against your own traffic, or get pricing and a security review.